API Rate Limiting Strategies for Developers
Compare fixed window, sliding window, token bucket and leaky bucket limiters, build them atomically with Redis Lua, and send RateLimit headers.
Reviewed by Maurice Sobiera
API rate limiting caps how many requests a client may send in a period, so one client cannot overload the service or crowd out others. For most public APIs, a sliding window counter is a good default: it is near-exact and uses constant memory per client. Use a token bucket if you want to allow bursts.
TL;DR:
- A sliding window counter balances accuracy and memory, which suits general public APIs with high traffic.
- Redis Lua scripts make the read, refill and consume steps atomic, so concurrent requests cannot race.
- A refill rate slightly above normal p99 traffic and a capacity of 5 to 10 seconds of burst are reasonable starting values.
- Tell clients their limits with RateLimit headers, and send Retry-After with every 429 response.
- Enforce limits at the edge and in the application, and decide per endpoint what happens when Redis is down.
Table of Contents
- How do the main rate-limiting algorithms compare?
- Implementation notes for each algorithm
- How do you build a limiter that works across instances?
- Which algorithm fits which endpoint?
- How should you tell clients about their limits?
- Setting refill rates, capacity, and alerts
- Where these patterns show up in production
- Fairness and abuse prevention
- Sources
- FAQ
How do the main rate-limiting algorithms compare?
Five algorithms cover almost every production case. Each sits at a different point between memory cost, burst tolerance and accuracy. The Redis rate limiting tutorial compares the same five, and the table below follows its structure.
| Algorithm | State per client | Accuracy | Burst behavior | Typical use |
|---|---|---|---|---|
| Fixed window | One counter | Approximate | Allows up to 2x the limit at window boundaries | Simple API limits, login throttling |
| Sliding window log | Sorted set of timestamps | Exact | No bursts | High-value APIs, audit trails |
| Sliding window counter | Two counters | Near-exact | Smoothed boundaries | General-purpose API limits |
| Token bucket | Hash with token count and refill time | Exact | Allows controlled bursts | Bursty traffic with an average rate cap |
| Leaky bucket | Hash with one or two fields | Exact | No bursts, steady drain | Policing or shaping traffic in front of a fragile backend |
Pick by the main constraint. Fixed window is the cheapest to run. Sliding window log is exact but its memory grows with request volume. Sliding window counter gives near-exact results with constant memory. Token bucket suits developer-facing APIs that need burst headroom, and leaky bucket suits queues in front of rate-sensitive backends.
Implementation notes for each algorithm
Each algorithm needs a specific state shape and has its own runtime cost, so picking one is really picking a data structure.
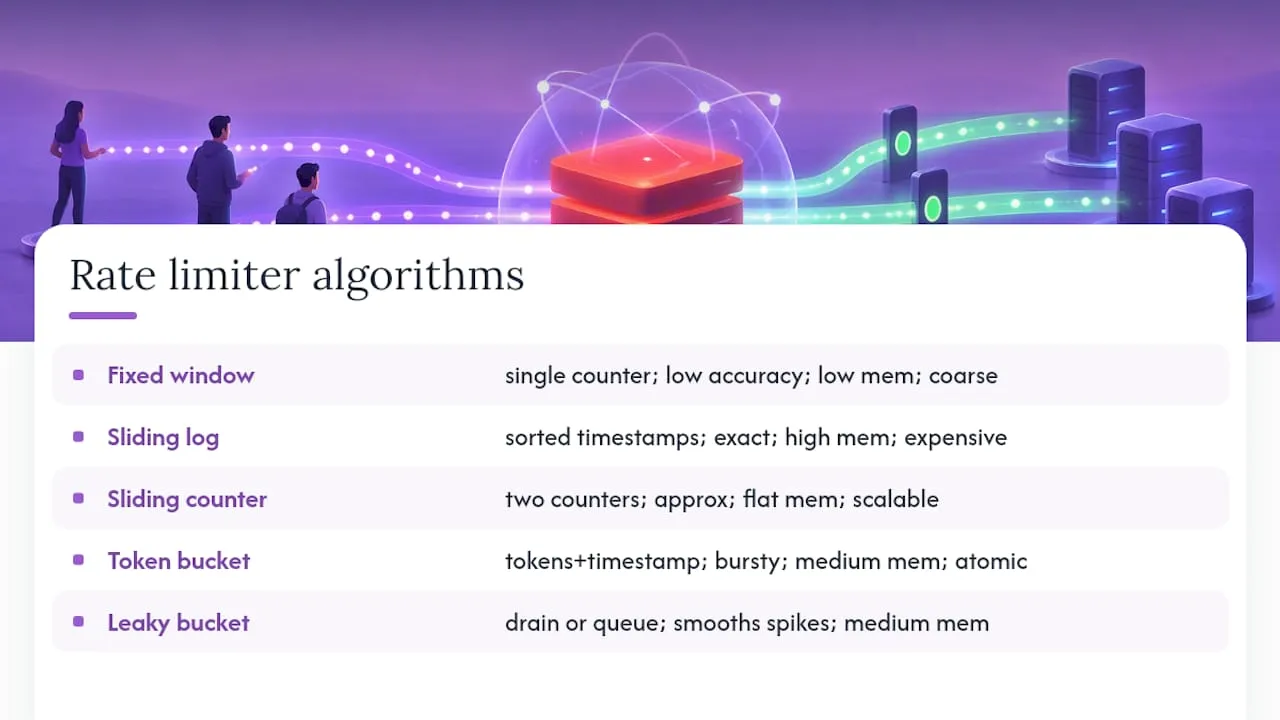
Fixed window stores one counter per client and time bucket. It increments on each request and resets when the bucket rolls over. The weakness is the boundary. With a limit of 100 requests per minute, a client can send 100 requests at 12:00:59 and another 100 at 12:01:00. That is 200 requests in two seconds, so use fixed window only for coarse, low-risk limits.
Sliding window log keeps a sorted set of request timestamps per client and trims entries older than the window on each check. It is exact because it counts real requests. Memory grows with request volume, which makes it expensive for high-traffic clients.
Sliding window counter stores two counters, one for the current window and one for the previous window. It weights the previous count by how much of that window still overlaps the sliding window. Take a limit of 100 per minute, 80 requests in the previous minute and 30 so far in the current one, 25 percent into the current minute. The estimate is 80 × 0.75 + 30 = 90. The client has about 10 requests left.
Cloudflare describes this approach for its rate limiting. It needs only two numbers per counter. In an analysis of 400 million requests from 270,000 distinct sources, 0.003 percent of requests were wrongly allowed or rate limited, according to Cloudflare.
Token bucket stores a token count and a last-refill timestamp per client. On each request you calculate the tokens earned since the last check, cap the total at the bucket capacity, and deduct one token if available. Refill and consume must happen atomically. Otherwise two concurrent requests can read the same token count, and both succeed when only one should.
Leaky bucket comes in two forms. The policing form drops requests that exceed the drain rate. The shaping form queues them for later processing. Use it when the endpoint sits in front of a database or third-party service that cannot absorb spikes.
Pro Tip: Wrap refill and consume in one Lua script instead of separate GET and SET calls. A read-then-write sequence across two round trips is the race condition that atomic scripts exist to prevent.
How do you build a limiter that works across instances?
Keep the counters in Redis and make every update atomic. A limiter that works in one process and fails under concurrency is worse than none, because it gives a false sense of protection.
- Store counters in Redis so every application instance reads and writes the same state.
- Use Redis Lua scripts to combine the read, refill and consume steps into one atomic operation. The Redis tutorial explains why: with separate commands, concurrent requests can read the same state, both decide they are allowed, and both write back.
- For high-volume services, aggregate counts locally per instance or per point of presence before syncing to a central store. This avoids a Redis call on every request.
- Add a gateway-level leaky bucket, for example in NGINX, as an outer wall against abusive traffic. Keep the finer per-key limits in the application.
- Decide between fail-open and fail-closed for each endpoint before an incident forces the decision.
Fail open on read-heavy public endpoints, so a Redis outage does not take the whole API down. Fail closed on authentication and payment endpoints, where unlimited traffic is the bigger risk.
Pro Tip: Log every fail-open event separately from normal traffic. A Redis outage that silently disables your limits tends to show up only in an incident review.
Which algorithm fits which endpoint?
Check four things before you write code. How much memory can you spend per client? Are bursts legitimate or a threat? How fragile is the downstream system? Are estimates acceptable instead of exact counts?
| Endpoint type | Suggested algorithm | Reason |
|---|---|---|
| Public developer APIs | Sliding window counter or token bucket | Both tolerate reasonable bursts without exact-count overhead |
| Payment and authentication | Sliding window log, or a fail-closed default | Exact counts, and rejecting is safer than letting suspicious traffic through |
| Flows limited by a downstream service | Leaky bucket | The output rate never exceeds what the backend can handle |
| High-volume, low-risk internal traffic | Fixed window | Simplest implementation, and boundary bursts are acceptable |
If you cannot say what happens when Redis is unreachable, the design is not finished, whichever algorithm you chose.
How should you tell clients about their limits?
Send the current limit state in response headers, and send Retry-After with every 429. Clients should not have to guess where they stand.
The IETF HTTP API working group is standardizing the headers in the Internet-Draft RateLimit header fields for HTTP. In the current revision (draft 11, May 2026), the RateLimit-Policy field describes the quota and the RateLimit field reports what is left:
RateLimit-Policy: "default";q=100;w=60RateLimit: "default";r=50;t=30Here q is the quota, w is the window in seconds, r is the remaining quota and t is the seconds until the window resets. This replaces the older draft revisions that used separate RateLimit-Limit, RateLimit-Remaining and RateLimit-Reset fields. Many APIs still send the vendor-prefixed X-RateLimit-* headers, which predate the draft. Because the draft is not final, check the current revision before you commit to a format.
A rejected request should use status 429, which RFC 6585 defines as Too Many Requests. The response may include a Retry-After header with the number of seconds to wait, as in the RFC’s example:
HTTP/1.1 429 Too Many RequestsRetry-After: 3600Follow these rules in practice:
- Send the limit headers on every response, not only on rejections.
- Send
Retry-Afterwhenever you reject with a 429. - Treat the headers as hints. The draft states that clients must not assume a positive available quota guarantees that further requests will be served.
- On the client, use exponential backoff with jitter instead of a fixed delay, so retries do not arrive in synchronized waves.
Setting refill rates, capacity, and alerts
Start from measured traffic, not from a guess. Pull p95 and p99 requests per second per client from your metrics, and set the refill rate a bit above the sustained p99 so normal usage never trips the limiter. Size the bucket capacity to absorb roughly 5 to 10 seconds of p99 traffic. These are starting values, not a standard.
For example, if one client has a p99 of 20 requests per second, a refill rate of 24 per second and a capacity of 200 tokens allows a burst of 200 requests. After that burst, the bucket needs 200 / 24, about 8.3 seconds, to refill completely.
Watch these signals after the limiter goes live:
- The 429 rate and throttle ratio as a share of all requests, not only raw counts.
- Latency for throttled and non-throttled traffic, tracked separately, since a rise in the first often comes before a rise in the second.
- Redis command failures or timeouts tied to the limiter, because a silent failure defeats the whole system.
Roll out limit changes to a small share of traffic first, then widen once the 429 rate and latency look stable.
Pro Tip: When you tighten a limit, announce the change and the new headers to API consumers before it ships. A surprise 429 with no context creates more support tickets than the abuse it was meant to stop.
Where these patterns show up in production
Most production stacks split enforcement across two layers.
- Edge: an NGINX leaky-bucket configuration absorbs abusive traffic and obvious scraping before it reaches application servers.
- Application: a Redis Lua script implementing token bucket or sliding window counter enforces per-key limits, usually failing open on read-only endpoints.
- Public developer APIs: sliding window counter or token bucket, tuned to the plan tier of the client.
- Authentication endpoints: strict, low-capacity limits, often fail-closed.
- Webhook processors: leaky bucket or a queue-backed limiter, because retries from the sending service need smoothing instead of outright rejection.
Fairness and abuse prevention
Rate limiting decides which requests get served when demand exceeds capacity, and that decision affects real users. A limit that is too strict locks out legitimate customers during a traffic spike. A limit that is too loose lets a few abusive clients degrade service for everyone.
Publish your limits in the API documentation, because undocumented throttling looks arbitrary. Apply limits consistently across similar clients. State in your terms what counts as abusive traffic, such as credential stuffing or scraping, as opposed to high-volume use by a paying customer.
For multi-tenant platforms, isolate limits per tenant. One customer’s spike, whether legitimate or malicious, then cannot use up the quota of another tenant on the same infrastructure.
Sources
- Build 5 Rate Limiters with Redis: Fixed Window, Sliding Window, Token Bucket, and Leaky Bucket
- RateLimit header fields for HTTP (IETF draft)
- Counting things: a lot of different things (Cloudflare)
- RFC 6585: Additional HTTP Status Codes
Recommended
Frequently asked questions
Combine an algorithm that fits the traffic pattern with atomic enforcement. A sliding window counter suits general APIs, and a token bucket suits bursty clients. Atomic enforcement means concurrent requests cannot bypass the limit. Edge limits plus per-key application limits add a second layer, as in Cloudflare’s approach.
Store counters or token state in a shared store like Redis, and wrap the read, refill and consume steps in one atomic Lua script. Return RateLimit headers on every response and a Retry-After header on rejections, so clients know how to behave.
Check your memory budget, burst tolerance and how fragile the downstream systems are. Then match an algorithm to those limits: sliding window counter or token bucket for public APIs, sliding window log or a fail-closed default for sensitive endpoints. Tune the refill rate from measured p99 traffic.
API rate limiting caps how many requests a client can make in a given period. It protects the service from overload and keeps usage fair across clients. Servers usually report the limit and the remaining quota in response headers, which the IETF RateLimit header draft is standardizing.
Ready to build this yourself? Get your API key — 7-day trial, no card required — or see the Blockchain API for the full endpoint reference.